01
Hong Kong Chum Call International Limited
Electronic components, inspected under X-ray.
A compact team of experts that quickly finds and inspects electronic components — with a personal manager instead of a ticket system.
- 4-step quality inspection, including X-ray
- Dedicated manager — replies within 24 hours
- Company founded in 2021 — our managers have worked in the industry since 2015
Grounded supply for a high-voltage world.
100+ years of combined industry expertise. One dedicated manager for your order.
FoundedLive
2021
Hong Kong · Private company limited by shares
20212026
TeamHong Kong
9experts
Combined experienceSince 2015
100+YEARS
One dedicated manager for every order
WarrantyOfficial supply channels
1year
Something wrong? Send a claim report — we re-supply, or refund scarce parts. EOL terms agreed individually.
Every order
Dedicated manager
Inspection report
Traceable origin
Global sourcing network
Quality control4 steps
- Visual InspectionPackaging, marking, body and leads01
- Microscope SurfaceSurface examination under a microscope02
- Functional TestingExtended testing in partner laboratories03
- X-ray InspectionAdditional check on an X-ray system04
What we supply
Hard-to-find and obsolete components — sourced, tested, delivered.
- Integrated Circuits
- Microcontrollers
- Memory
- Power
- Passives
- Connectors
02
Server Equipment
- Rack & Blade Serversi
- CPUs & GPUsi
- Server Memoryi
- Storage (SSD / HDD)i
- Networkingi
- Power Suppliesi
Rack & Blade ServersExamples for AI training · pricing on request
$Entry
Dell PowerEdge R760xa
2U · 2× Intel Xeon Scalable (4th/5th Gen) · up to 4 double-width PCIe GPUs
A compact GPU server for fine-tuning mid-size models, running LoRA experiments and serving trained models in production.
Lenovo ThinkSystem SR665 V3
2U · 2× AMD EPYC 9004 · up to 3 double-width GPUs · DDR5
Cost-efficient node for prototyping, data preprocessing and fine-tuning open-source LLMs on a single machine.
$$Mid-range
Supermicro SYS-421GE-TNRT
4U · 2× Intel Xeon · up to 10 double-width PCIe GPUs (e.g. L40S, H100 NVL)
High GPU density in one chassis — trains vision and language models across many GPUs without building a cluster.
Lenovo ThinkSystem SR675 V3
3U · 2× AMD EPYC 9004 · up to 8 double-width GPUs or NVIDIA HGX 4-GPU
Flexible building block for growing AI teams: start with PCIe GPUs, move to an HGX board as models get larger.
$$$Flagship
NVIDIA DGX H100
8× H100 SXM5 80 GB · NVLink / NVSwitch · 2 TB RAM · 8× ConnectX-7 400G
Turnkey system for training foundation models; scales into multi-node DGX SuperPOD clusters.
Dell PowerEdge XE9680
6U · 8× NVIDIA H100 / H200 SXM5 or AMD MI300X · NVLink
Flagship 8-GPU server for large-scale LLM pre-training and high-throughput generative AI.
CPUs & GPUsExamples for AI training · pricing on request
$Entry
NVIDIA L4 24 GB
Ada Lovelace · low-profile · 72 W · FP8
Energy-efficient GPU for inference, video AI and light fine-tuning — fits almost any standard server.
AMD EPYC 9254
24 cores · Zen 4 · 12-channel DDR5 · 128 PCIe 5.0 lanes
Host CPU that keeps GPUs fed: data loading, augmentation and orchestration in training nodes.
$$Mid-range
NVIDIA L40S 48 GB
Ada Lovelace · 48 GB GDDR6 · FP8 Transformer Engine
Versatile data-center GPU for fine-tuning, generative AI and mixed training / inference workloads.
Intel Xeon Platinum 8480+
56 cores · Intel AMX · 8-channel DDR5
The CPU used in HGX / DGX H100 systems; AMX accelerates CPU-side preprocessing and inference.
$$$Flagship
NVIDIA H100 SXM5 80 GB
HBM3 · 3.35 TB/s · NVLink 900 GB/s · FP8
The industry standard for LLM training; Transformer Engine speeds up large-model training.
AMD Instinct MI300X 192 GB
HBM3 · 5.3 TB/s · CDNA 3
Very large on-board memory: trains and serves big models on fewer GPUs.
Server MemoryExamples for AI training · pricing on request
$Entry
DDR4-3200 RDIMM 32 GB
Samsung · SK hynix · Micron · ECC registered
Upgrades for existing Xeon 3rd Gen / EPYC 7003 GPU servers and data-loading nodes.
DDR5-4800 RDIMM 32 GB
Samsung · SK hynix · Micron · ECC registered
Entry configuration for current-generation training servers and development nodes.
$$Mid-range
DDR5-4800 RDIMM 64 GB
Dual-rank · ECC registered · 1 TB per 2-socket node with 16 modules
Balanced memory for training nodes: caches datasets and keeps GPU pipelines saturated.
DDR5-5600 RDIMM 64 GB
For Xeon 5th Gen and EPYC 9005 platforms
Higher bandwidth for data-heavy preprocessing and CPU-assisted training.
$$$Flagship
DDR5 RDIMM 128 GB
High-capacity registered DIMM · 2 TB per node
DGX-class memory capacity for large batches and in-memory training datasets.
DDR5 3DS RDIMM 256 GB
3D-stacked · up to 4–6 TB per node
Huge embedding tables, vector databases and CPU offload of model states (e.g. ZeRO-Offload).
Storage (SSD / HDD)Examples for AI training · pricing on request
$Entry
Seagate Exos X20 20 TB
Enterprise HDD · 7,200 rpm · SATA / SAS
Low-cost bulk storage for raw datasets, archives and model checkpoints.
Samsung PM893 3.84 TB
Enterprise SATA SSD · high endurance
Boot and OS drives, small datasets and logs on training and inference nodes.
$$Mid-range
Samsung PM9A3 7.68 TB
NVMe U.2 · PCIe 4.0
Fast local scratch space for training data next to the GPUs.
Micron 7450 PRO 7.68 TB
NVMe · PCIe 4.0 · U.3 / E1.S
Dataset cache and fast checkpointing for multi-GPU training runs.
$$$Flagship
KIOXIA CM7-R 15.36 TB
NVMe · PCIe 5.0 · ~14 GB/s sequential read
Feeds multi-GPU nodes at full speed; suited to GPUDirect Storage pipelines.
Solidigm D5-P5336 61.44 TB
High-capacity QLC NVMe · PCIe 4.0
Dense, fast data lakes for training corpora — petabytes in a few racks.
NetworkingExamples for AI training · pricing on request
$Entry
NVIDIA ConnectX-6 Lx 25GbE
Dual-port · RoCE · PCIe 4.0
Management and storage networking for small GPU clusters.
Intel Ethernet E810-CQDA2 100GbE
Dual-port 100G · RDMA (iWARP / RoCEv2)
Affordable 100G links for storage traffic and inference clusters.
$$Mid-range
NVIDIA ConnectX-6 HDR 200Gb/s
InfiniBand HDR / 200GbE · GPUDirect RDMA
Low-latency interconnect for multi-node training in small and mid-size clusters.
NVIDIA ConnectX-7 400Gb/s
InfiniBand NDR / 400GbE · PCIe 5.0 · GPUDirect RDMA
The adapter used in current H100 clusters — direct GPU-to-GPU traffic between nodes.
$$$Flagship
NVIDIA Quantum-2 QM9700
64× NDR 400Gb/s InfiniBand ports · SHARP in-network computing
Switch fabric for large GPU clusters; accelerates collective operations during training.
NVIDIA Spectrum-4 SN5600
64× 800GbE · Spectrum-X AI Ethernet
Ethernet fabric built for AI clouds at hyperscale.
Power SuppliesExamples for AI training · pricing on request
$Entry
1,400 W Platinum hot-plug PSU
Dell / HPE OEM · redundant pair
Power for 1–2 GPU servers and storage nodes.
1,600 W Platinum Flex Slot PSU
HPE ProLiant Gen10 / Gen11 · hot-plug
Redundant power for entry GPU configurations.
$$Mid-range
2,000 W Titanium PSU
Supermicro · 96% efficiency · redundant
For 4–8 PCIe GPU nodes — lower energy loss in 24/7 training.
2,400 W Titanium PSU
Delta / Lite-On OEM · hot-plug
Headroom for dense 8-GPU PCIe servers under sustained load.
$$$Flagship
3,000 W Titanium PSU
For NVIDIA HGX 8-GPU systems · N+N redundancy
Keeps 8× SXM GPU systems running at full power during long training runs.
3-phase rack PDU 30–60 kW
Vertiv / APC · metered, switched
Power distribution for AI racks with several 8-GPU servers.
03
PCB Boards
- Single & Double-Sided
- Multilayer
- HDI
- Flexible (FPC)
- Rigid-Flex
- PCB Assembly
Quality Control
Every component inspected. Every shipment traceable.
-
STEP 01
Visual Inspection
Packaging, marking, body and lead condition.
-
STEP 02
Microscope Surface Inspection
Surface examination under a microscope.
-
STEP 03
Functional Testing
Extended functional testing in partner laboratories.
-
STEP 04
X-ray Inspection
Additional check on an X-ray system.
Process
How we work
- 01
Send your list
Part numbers or a full BOM.
- 02
Get a quote
Within 24 hours.
- 03
Confirmation
Availability, price and lead time confirmed.
- 04
Agreement & order
Terms agreed, order placed.
- 05
Inspection
4 steps, including X-ray.
- 06
Shipping
Traceable delivery.
- 07
Post-shipping service
Support after delivery.
Why CHUM CALL
Real people. Verified parts.
01
Dedicated manager
One person for your order — from quote to delivery.
02
4-step inspection
Visual, microscope, functional and X-ray checks.
03
Rare & EOL sourcing
Hard-to-find and obsolete components.
04
Transparency
Origin, inspection report and clear warranty terms.
Team
Always in touch with you.
Real people, not a ticket system — one dedicated manager for your order. Our managers have worked in the industry since 2015, long before CHUM CALL was founded in 2021.
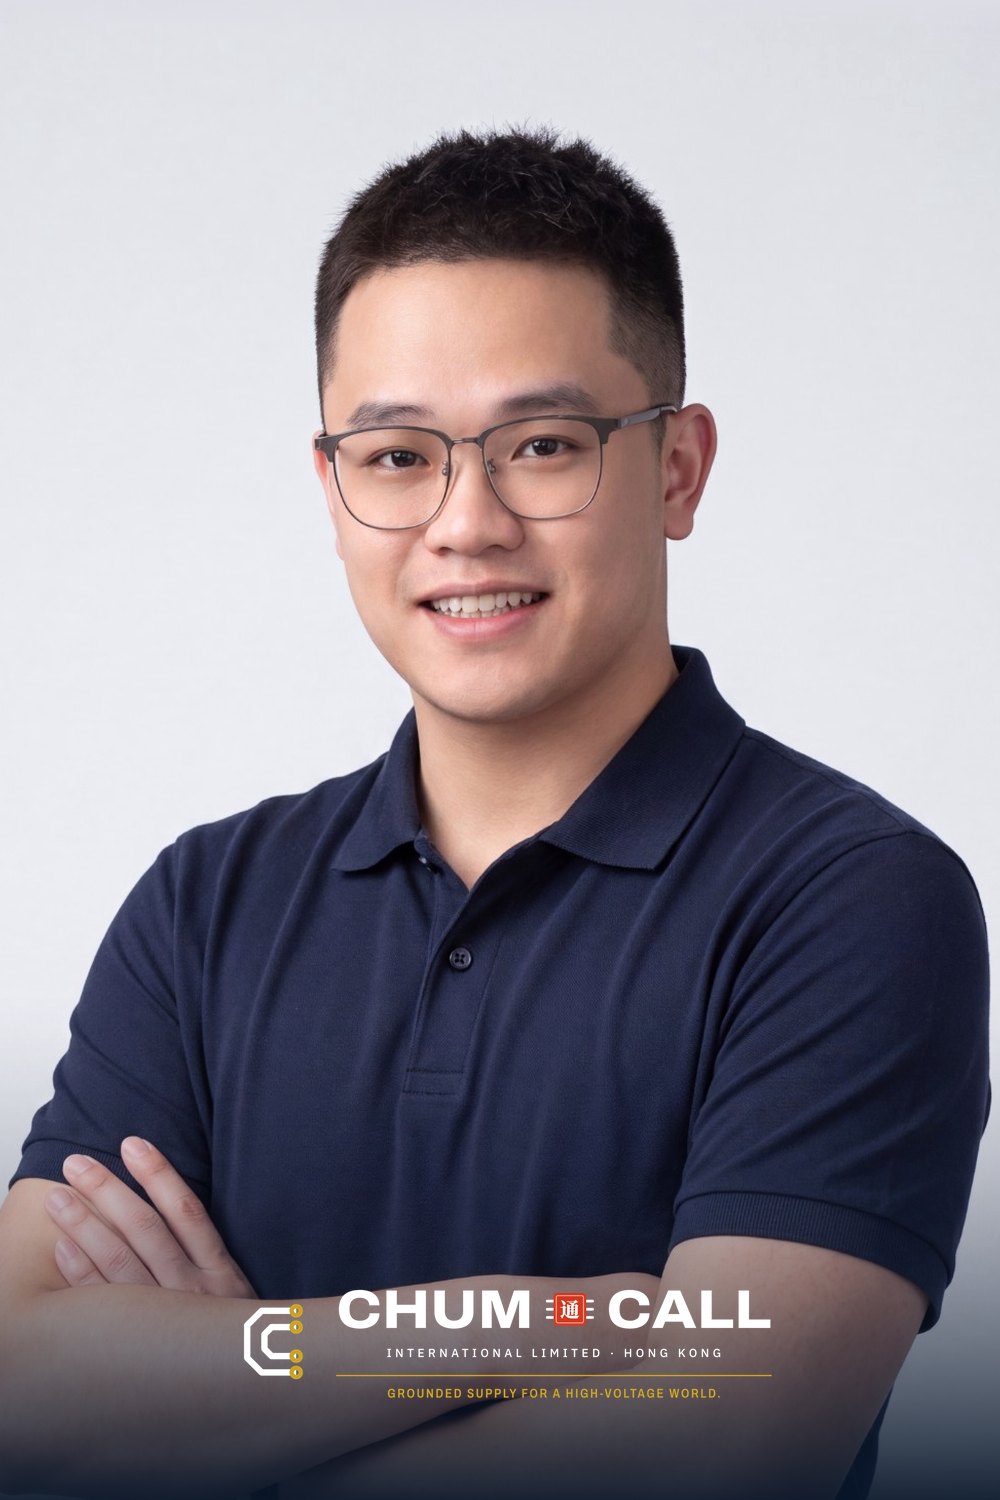
RyanHead of Procurement
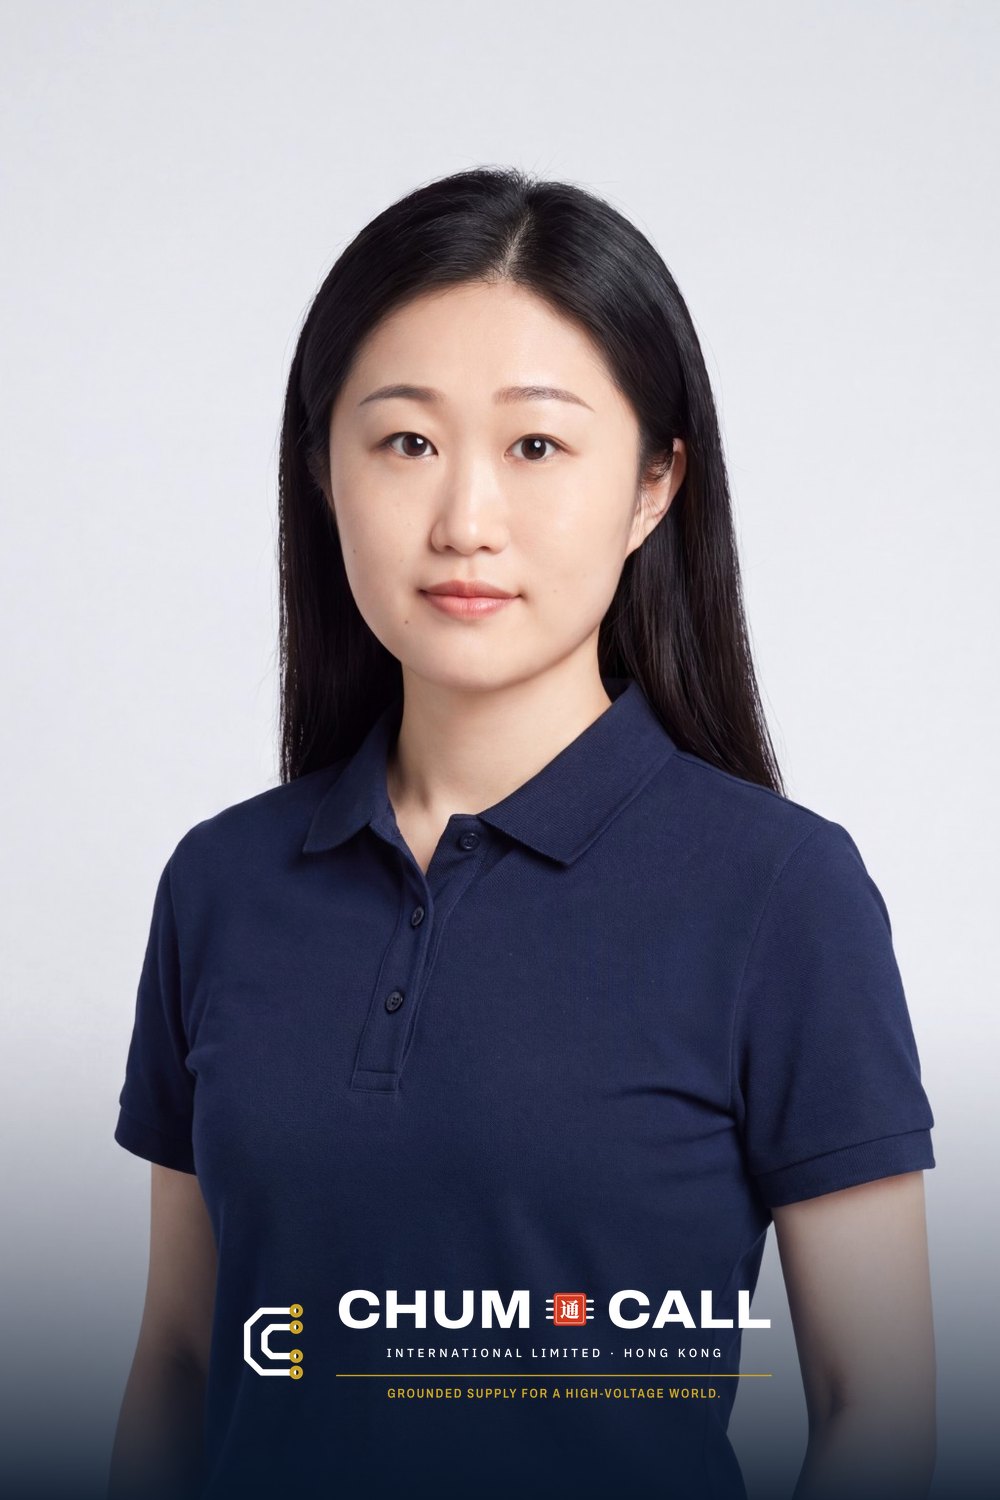
DianaHead of Sales
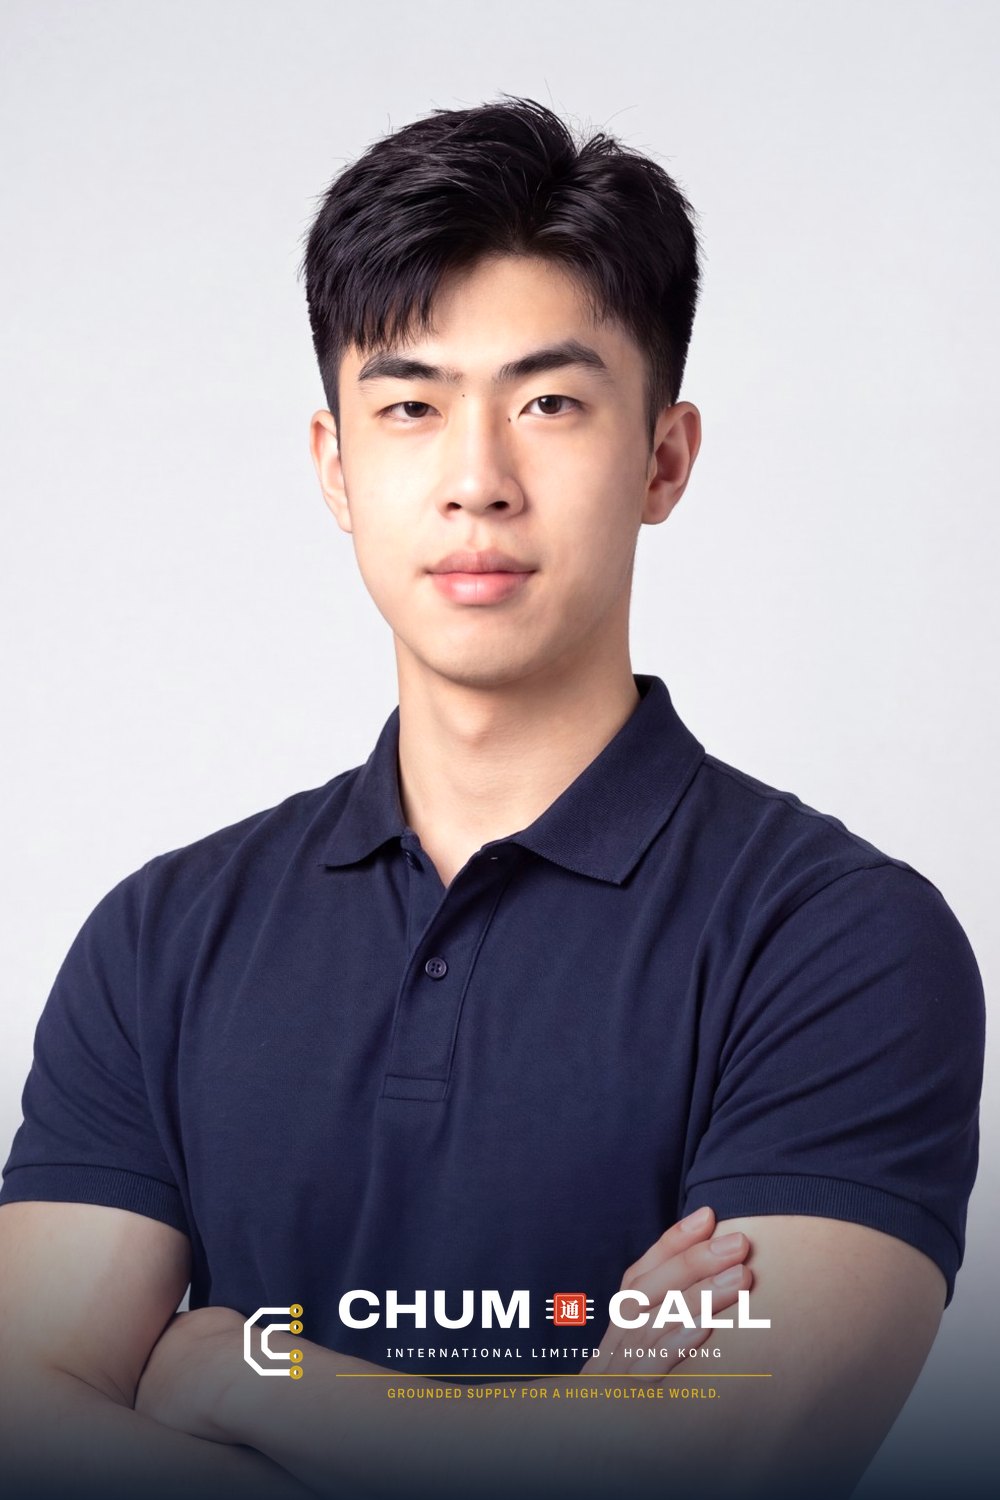
YohanSales Manager
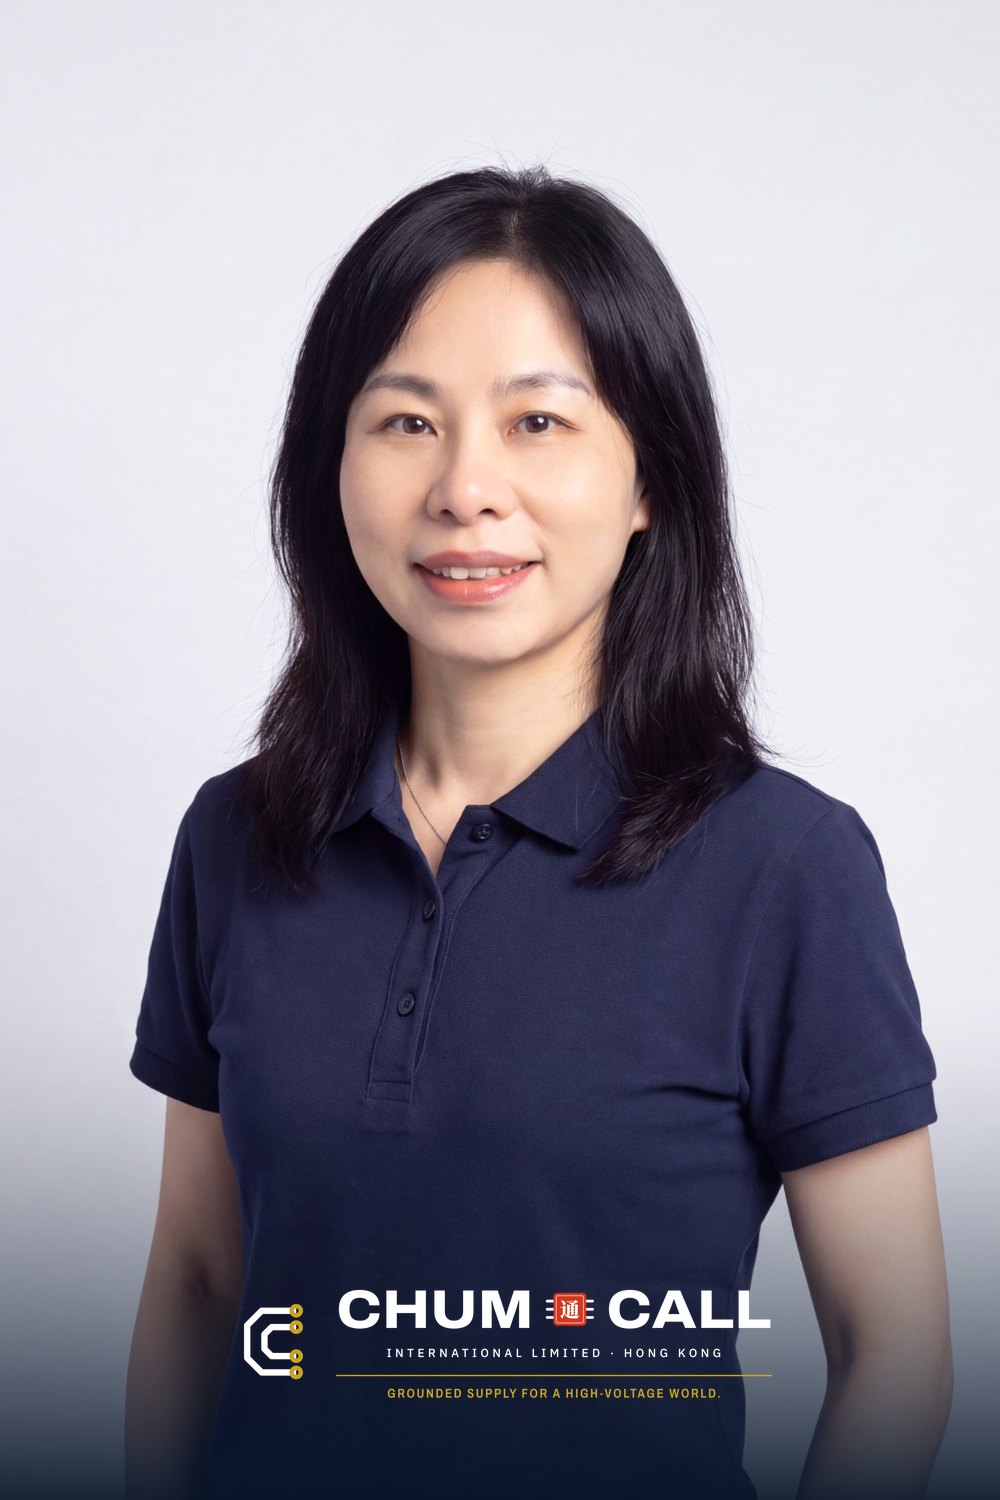
CandyHead of Finance & Accounting
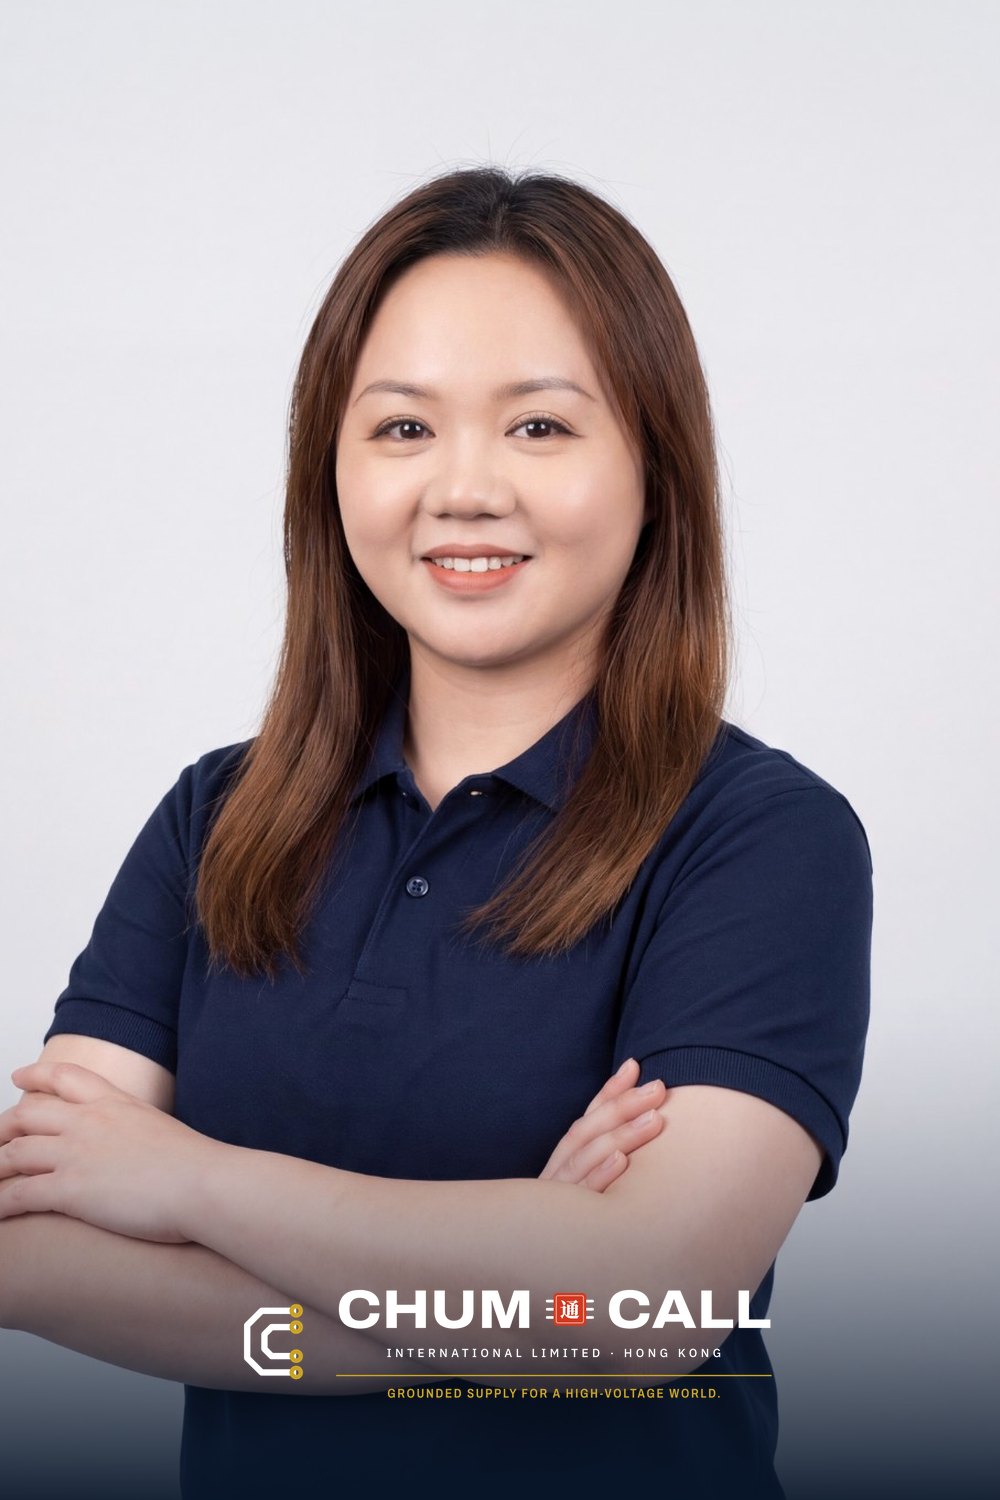
ChristinaProject Manager
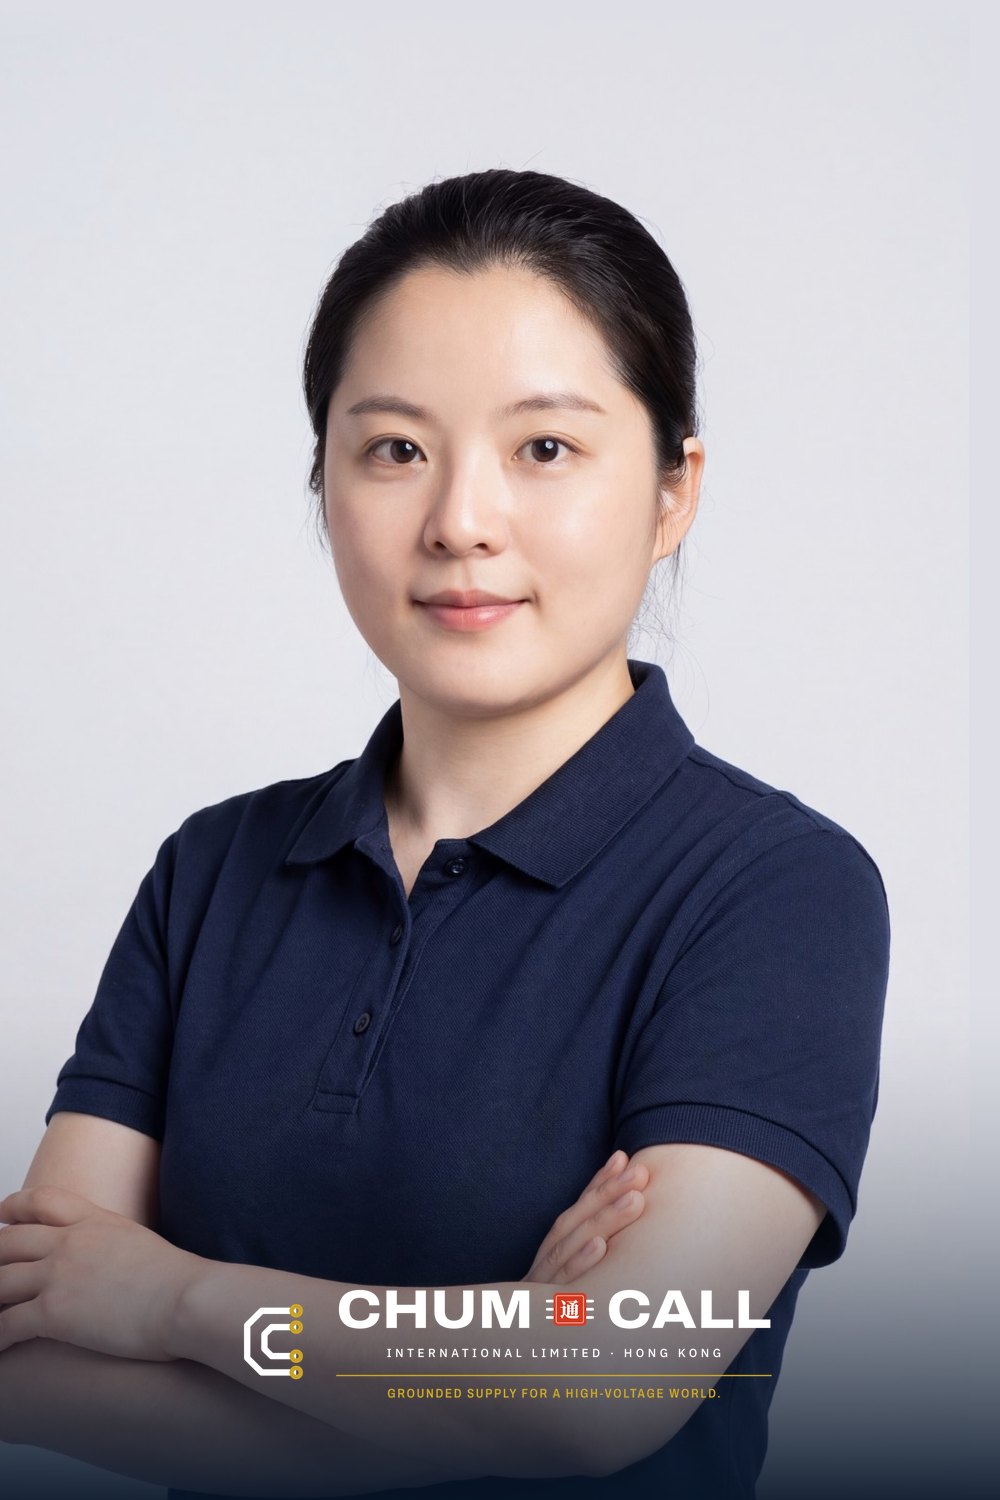
RachelLogistics Manager
FAQ
Questions
What is your minimum order quantity (MOQ)?
MOQ is set individually for each part number. Send us your request and we will reply with up-to-date terms.
Which payment methods and delivery terms do you offer?
We accept bank transfers to banks in Hong Kong and mainland China. Other payment options can be discussed individually with your manager.
Delivery terms (Incoterms® 2020): EXW Shenzhen, EXW Hong Kong, FCA Shenzhen.
How do you ship and how long does delivery take?
For in-stock items, documentation and dispatch usually take around 14 days. If you have other requirements, we review the options together with you — balancing lead time and cost across the solutions offered by our logistics partners.
Do you provide a warranty?
Our products come from official supply channels and are covered by a 1-year warranty. For hard-to-find, discontinued (EOL) or older date-code parts, warranty terms are agreed individually.
What if something goes wrong?
Please send us a claim report describing the issue — as soon as we receive it, we arrange the return. Standard parts are re-supplied; for scarce or hard-to-find parts, where a replacement cannot be guaranteed, we refund your payment.
If something goes wrong
Send us a claim report — we arrange the return straight away.
- Your claim reportReturn arranged
- Standard partsRe-supplied
- Scarce partsRefunded
How quickly will I get a quote?
We reply within 24 hours. A response may take longer only on weekends and public holidays, or when the requested part is particularly complex or specialised.
Will I receive an inspection report?
Yes. A test report is provided on request in advance — free of charge.
Request a Quote
Send your list.
Your dedicated manager replies within 24 hours.
sales01@hk-chumcall.com
Reply within 24 hours